You built a chatbot. It works great in demos. Then you put it in production, and it starts hallucinating customer data or executing SQL queries that delete tables. Sound familiar? The gap between "cool demo" and "reliable product" is where most LLM agents fail.
By mid-2025, the industry realized that throwing more parameters at a model doesn't fix structural flaws. We need architectural discipline. Leading platforms like Databricks, Google, and Anthropic have shifted from ad-hoc prompting to formalized agent design patterns. These aren't just theoretical concepts; they are battle-tested strategies to keep your AI safe, predictable, and easy to debug.
The Complexity Continuum: Choosing Your Architecture
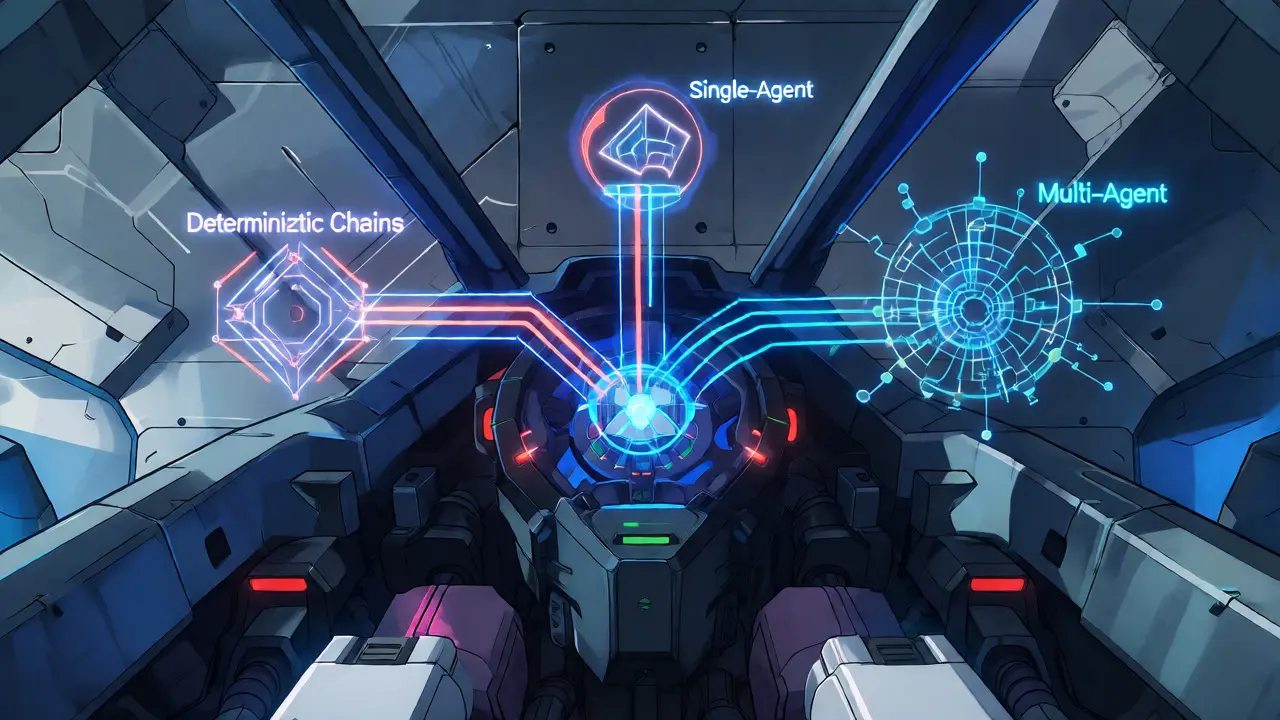
Before writing code, you must decide how much autonomy your agent gets. This isn't a binary choice. It's a spectrum. Databricks' documentation identifies three primary categories, each with distinct trade-offs in latency, cost, and flexibility.
| Architecture | Decision Authority | Predictability | Best For |
|---|---|---|---|
| Deterministic Chains | Developer-defined workflow | Very High (95%+ accuracy) | Regulated financial transactions, strict compliance tasks |
| Single-Agent Systems | LLM selects tools dynamically | Moderate | Enterprise support bots, dynamic data retrieval |
| Multi-Agent Systems | Specialized agents coordinate | Low (High coordination overhead) | Complex research, coding assistants, creative workflows |
Deterministic chains are the safest bet. You hard-code the steps. The LLM has no say in which tool runs next. If you're processing loan applications, this is often all you need. Single-agent systems let the model choose tools based on user intent. This is what Databricks calls the "sweet spot" for many enterprise use cases because it balances flexibility with debuggability. Multi-agent setups are powerful but expensive. Each additional agent call increases token usage and latency. As Vellum AI noted in their January 2026 guide, a single agent with strong prompts often matches the performance of complex multi-agent swarms in specific contexts. Don't add complexity unless you have to.
Security First: Mitigating Prompt Injection
Here is the uncomfortable truth: once an agent ingests untrusted input, it becomes vulnerable. Luca Beurer-Kellner’s team at cusy.io highlighted that 78% of security professionals consider prompt injection their top concern for agent deployment. A malicious user can hide instructions in a PDF resume or a website comment, tricking your agent into leaking data or performing unauthorized actions.
To counter this, adopt the Plan-Then-Execute Pattern. In this pattern, the agent plans its tool calls before ever touching untrusted content. The plan is generated in a clean context. Only after the plan is validated does the agent execute the tools against the raw data. This separation prevents malicious inputs from altering the execution path mid-stream.
Another critical strategy is Context-Minimization. Instead of feeding raw HTML or messy text directly to your main reasoning engine, pass it through a quarantined LLM first. This smaller, restricted model converts the input into a strictly formatted JSON interface. If the output doesn't match the schema, you reject it. This adds computational overhead but drastically reduces the attack surface. Remember, if your agent can read it, it can be manipulated by it.
Reliability Through Reflection and Critique
Agents fail silently. They don't crash; they just give wrong answers confidently. To catch these errors, implement the Reflect and Critique pattern. Before finalizing a response, the agent reviews its own output against the original goal and constraints. MongoDB’s design patterns catalog suggests this self-review loop can reduce error rates by approximately 35% in controlled tests.
Think of it as a second opinion. You might ask the agent: "Does this answer fully address the user's question? Did you cite sources correctly? Is there any contradictory information?" By forcing the model to critique itself, you create a buffer against hallucinations. This is especially vital when dealing with factual queries where precision matters. However, be mindful of costs. Every reflection step doubles your token usage. Use this pattern selectively, perhaps only for high-stakes interactions like medical advice or legal summaries.
Maintainability: Logging and Version Pinning
Debugging an agent is harder than debugging traditional software because the logic is probabilistic. When an agent fails, you need to know exactly what happened. Detailed logging is non-negotiable. You must log every user request, every intermediate plan, and every tool call. Tools like MLflow Tracing help visualize these chains. Without this visibility, you're flying blind.
Another maintenance nightmare is model drift. Providers update their models frequently. A change in GPT-4o or Claude 3.5 Sonnet can break your carefully tuned prompts. Databricks recommends version pinning and frequent regression tests. Lock your dependencies. Run your test suite whenever the provider announces an update. If you skip this, you'll wake up one day to find your agent behaving erratically, and you won't know why.
Hybrid Approaches: Structure Where It Helps
The debate between rigid workflows and autonomous agents is over. The winners use both. LlamaIndex advocates for a pragmatic middle ground: "use structure where it helps, provide autonomy where it shines." This means building hybrid systems. Start with a deterministic workflow for the core process. Introduce agent-like decision-making only at specific branching points where ambiguity exists.
For example, a customer service bot might follow a strict script for password resets (deterministic) but use an agent to handle complex billing disputes (autonomous). This approach minimizes risk while maximizing utility. It also makes the system easier to maintain. You can tweak the autonomous parts without breaking the entire flow. Google’s ADK framework supports this via Sequential Pipeline patterns, allowing structured handoffs between specialized agents.
Key Takeaways
- Start Simple: Most problems don't need multi-agent swarms. Try deterministic chains or single agents first.
- Isolate Untrusted Input: Use Plan-Then-Execute or Context-Minimization to prevent prompt injection.
- Log Everything: You cannot debug what you cannot see. Trace every step of the agent's reasoning.
- Pin Your Models: Provider updates can break your logic. Test rigorously before deploying changes.
- Reflect Before Acting: Self-critique loops significantly reduce hallucination rates in high-stakes scenarios.
When should I use a multi-agent system instead of a single agent?
Use multi-agent systems only when tasks require distinct specializations that conflict in a single prompt, such as separating coding logic from creative writing, or when parallel processing significantly speeds up complex workflows. For most enterprise applications, a well-prompted single agent with access to multiple tools performs nearly identically to multi-agent setups but with lower latency and cost.
How do I protect my LLM agent from prompt injection attacks?
Implement the Plan-Then-Execute pattern to separate planning from execution using untrusted data. Additionally, use Context-Minimization by passing raw inputs through a restricted, isolated LLM that outputs strictly formatted JSON before the main agent processes it. Never allow direct execution of commands derived solely from user-generated content without validation.
What is the biggest challenge in maintaining LLM agents?
Model drift and lack of observability. Providers frequently update underlying models, which can alter behavior unexpectedly. Without detailed logging of every step, including tool calls and intermediate thoughts, debugging these subtle shifts becomes nearly impossible. Version pinning and automated regression testing are essential mitigation strategies.
Do design patterns increase latency and cost?
Yes, generally. Patterns like Reflect and Critique or multi-agent coordination involve additional LLM calls, increasing both time-to-response and token consumption. Anthropic notes that agentic systems often trade latency and cost for better task performance. Therefore, apply these patterns selectively based on the criticality of the task rather than universally.
Can deterministic chains handle unexpected user queries?
Poorly. Deterministic chains rely on predefined workflows and struggle with novel or ambiguous inputs outside their scripted paths. They excel in high-reliability scenarios with clear boundaries, such as regulated financial transactions, but fail when flexibility is required. For unpredictable inputs, single-agent systems with dynamic tool selection are superior.
Art HND
Over-engineered nonsense for 90% of use cases.
Dave Gibbeson
Listen up! You cannot ignore the complexity continuum. If you are building financial tools, deterministic chains are non-negotiable. Stop trying to be clever with multi-agent swarms when a simple script works better. Save your tokens and your sanity by starting simple.
Meagan Mueller
theyre just hiding the real issue
the models are fundamentally broken and no amount of "patterns" fixes that
big tech wants us to buy their frameworks so they can charge us more while our data gets leaked in the background
prompt injection is inevitable because they cant actually understand language they just predict tokens
we are all just feeding them garbage and hoping it doesnt eat our servers
Sabrina Newland
this is such a deep topic 🤔 i wonder if the reflection patterns actually make the agents more human or just more confused 😅
like if an agent critiques itself does it become self-conscious? 🧠✨
i feel like we are missing the philosophical angle here about what reliability even means for a probabilistic mind 💭🌿
Mark Harvey
love the focus on logging here
its so easy to get lost in the black box without good tracing
keep pushing for observability its the only way to sleep at night
Amara Akbar
It is indeed crucial to maintain a balanced perspective on these architectural decisions.
While the technical details are important, we must also consider the human impact of deploying these systems responsibly.
Ensuring that our agents are both reliable and ethical requires a supportive approach to development and testing.
We should encourage teams to adopt these patterns gradually rather than overwhelming them with too many changes at once.
Collaboration between developers and stakeholders will help us navigate this transition smoothly.
Courtney Wagstaff
honestly this whole thing feels like a giant rainbow of confusion 🌈✨
you guys are talking about "deterministic chains" like its not basically just a fancy if-else statement wearing a tuxedo 🎩
and dont even get me started on the "reflection" part
its like asking a goldfish to remember its own thoughts before it forgets them again 🐠💭
we keep adding layers and layers of abstraction until nobody knows why the bot said "hello" instead of "hi"
it feels like we are painting over cracks in the foundation with glitter glue ✨🖌️
sure the demo looks pretty but when production hits it all turns into gray sludge 🌫️
im just vibing with the idea that maybe we should stop trying to make AI think like humans and let it be weirdly alien 🛸
but hey who am i im just watching the train wreck from the platform 🚂💨