Tag: LLM inference
2Nov
Flash Attention and Memory Optimizations for Faster LLM Inference
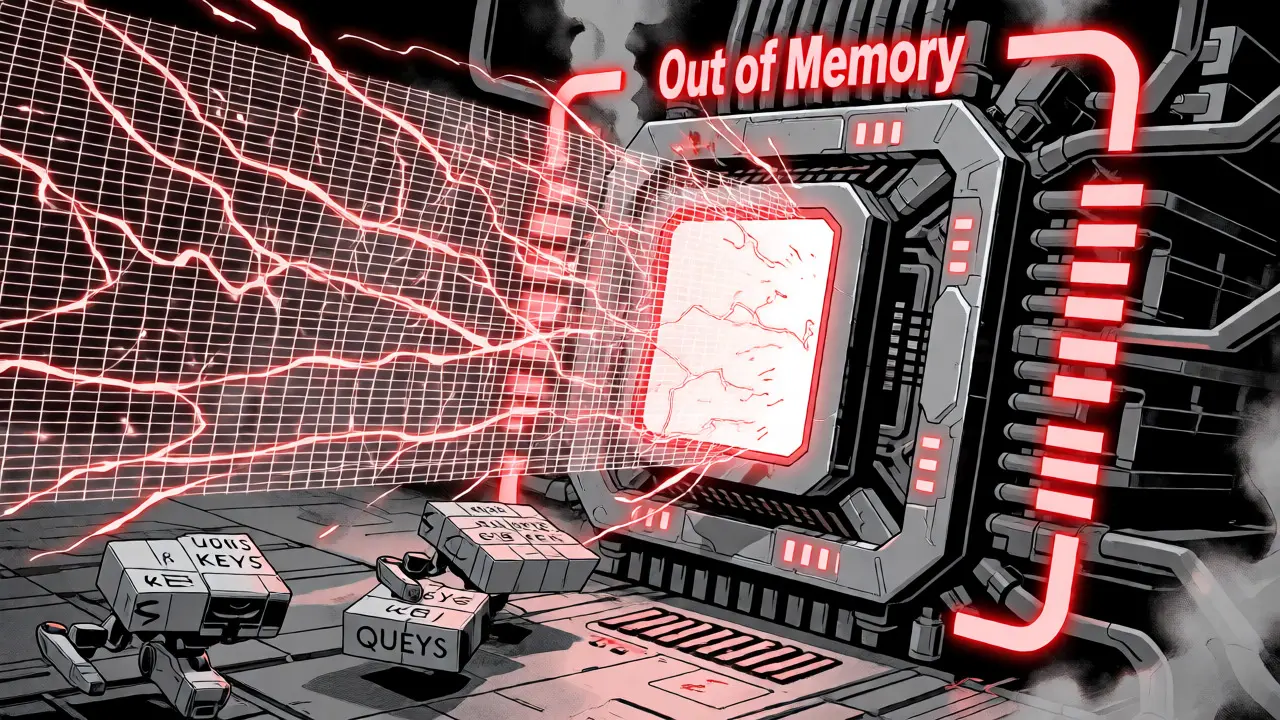
Discover how Flash Attention revolutionizes LLM inference by optimizing GPU memory usage. Learn about tiling, kernel fusion, and real-world speedups.
4Jul
GPU Selection for LLM Inference: A100 vs H100 vs CPU Offloading
Compare NVIDIA A100 vs H100 for LLM inference. Learn when to use CPU offloading. Real-world benchmarks, cost analysis, and decision frameworks for 2026 deployment.