You just bought a premium subscription to an advanced Large Language Model (LLM). The whole team is excited. But two weeks later, you get a scary email from your compliance officer. Someone in the marketing department pasted confidential client financial data into the chatbot, and it’s now sitting on a third-party server. This isn't just a hypothetical; it's the daily reality of LLM access controls. If you're running a business with AI tools, figuring out who can use which models-and why-is no longer optional. It’s the difference between innovation and a lawsuit.
The New Security Frontier: Why Old Rules Don't Work
Traditional cybersecurity was built for clear boundaries. You had a firewall, a user database, and specific applications. But LLMs blur those lines. They are dynamic, generative, and often connected to vast external data sources. As of late 2025, the field of Model Access Control has evolved from simple password gates to sophisticated frameworks that monitor what users ask, what the model retrieves, and what it spits back out.
Think about it this way: In a standard app, if you don't have permission to see a database table, you simply can't query it. With an LLM, a user might not have direct access to a sensitive document, but they could ask the AI to "summarize the key risks mentioned in recent internal memos." If the retrieval system isn't locked down, the AI might fetch and summarize that private memo anyway. This is why generic SaaS security fails here. You need controls that understand context, not just identity.
Core Architectures: RBAC vs. CBAC
Most organizations start with Role-Based Access Control (RBAC). It’s familiar. Admins assign roles like "Editor," "Viewer," or "Admin," and each role gets access to certain models. According to Cerbos.dev, about 68% of enterprises still rely primarily on basic RBAC. It’s easy to set up, but it has a massive blind spot: it doesn't care what you’re asking. An "Editor" might be allowed to use GPT-4o, but should they be able to use it to analyze HR salary data? Basic RBAC says yes. That’s a problem.
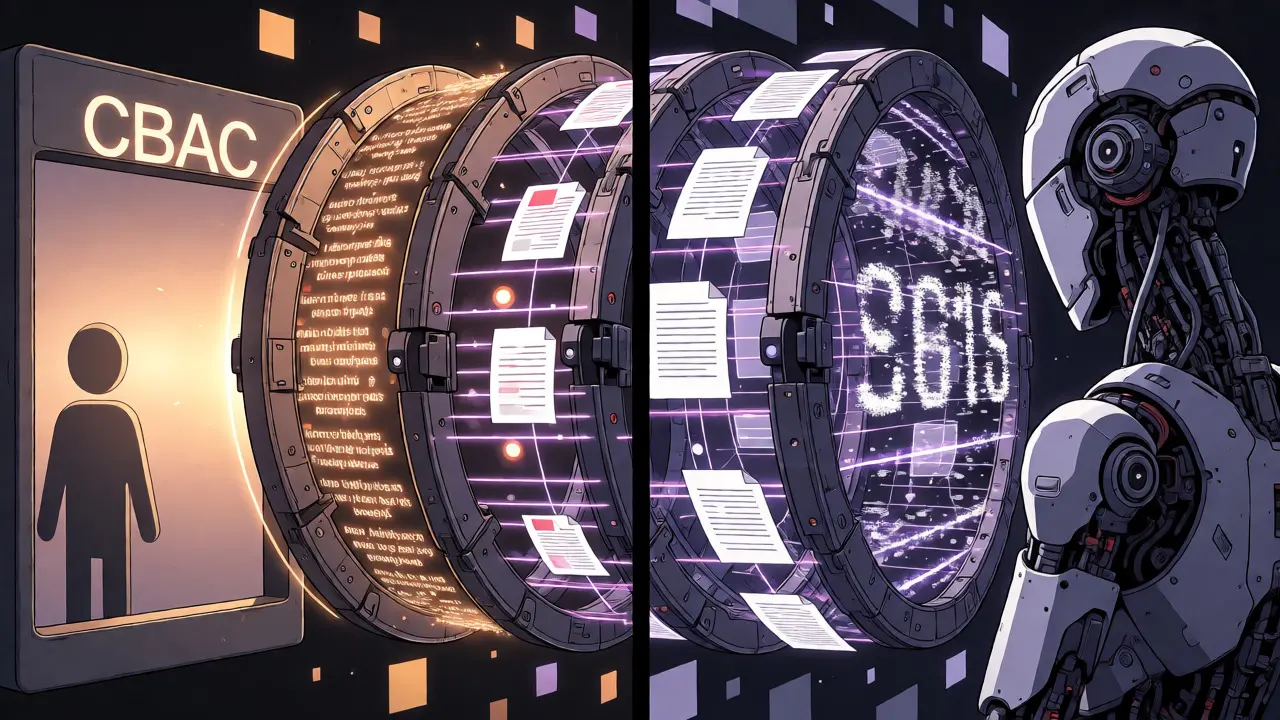
This is where Context-Based Access Control (CBAC) comes in. Advanced implementations enforce permissions at three critical layers:
- The Prompt Layer: What questions can the user actually type? Are they blocked from asking about specific proprietary codebases?
- The Retrieval Layer: If the AI uses RAG (Retrieval-Augmented Generation), which documents is it allowed to search? A junior analyst shouldn’t trigger searches through executive-only folders.
- The Output Layer: What can the model return? Even if it finds the data, does it mask the social security numbers before showing the answer?
Only about 27% of companies have moved to hybrid RBAC-CBAC systems because they require significant configuration effort. But if you handle Protected Health Information (PHI) or financial records, you likely need this level of granularity.
The Multi-Provider Headache
Very few companies stick to one LLM provider anymore. You might use OpenAI for creative writing, Anthropic for coding, and a local Llama 3 instance for sensitive internal data. Managing access across these silos is a nightmare. Portkey.ai reports that 89% of organizations using multiple providers face significant access control challenges.
| Approach | Adoption Rate | Best For | Main Weakness |
|---|---|---|---|
| Basic RBAC | 68% | Small teams, low-risk data | Ignores prompt content; high leakage risk |
| Hybrid RBAC-CBAC | 27% | Regulated industries (Finance, Health) | Complex setup; higher latency |
| LLM-Powered Analysis | 5% | Detecting anomalies in real-time | Expensive; potential for hallucinations |
The solution often lies in a gateway layer-a proxy that sits between your users and the various API endpoints. Tools like DataSunrise or specialized gateways allow you to define policies once and apply them everywhere. For example, you can create a rule that says, "If the input contains a credit card number, block the request regardless of which model is being called." This centralizes control so you aren't juggling five different dashboards.
Who Should Get Access? Defining Your Tiers
Not everyone needs access to the most expensive, capable models. High-end models like GPT-4o or Claude 3.5 Sonnet cost more per token and often process data differently than smaller, local models. Here is a practical tiering strategy used by mature enterprises:
- Tier 1: General Staff. Access to smaller, cheaper models (like GPT-3.5 or Llama 3 8B) for drafting emails, summarizing public news, or brainstorming. No access to proprietary company data via RAG.
- Tier 2: Knowledge Workers. Access to mid-tier models with limited RAG capabilities. They can query internal wikis or documentation but cannot upload new files or access raw SQL databases.
- Tier 3: Power Users & Developers. Full access to premium models, API keys, and complex RAG pipelines. They can experiment with fine-tuning and long-context windows.
- Tier 4: Admins & Compliance. Visibility into logs, ability to adjust guardrails, and access to audit trails for all other tiers.
This structure prevents bill shock. Why pay for premium tokens when a free intern is just trying to fix grammar? More importantly, it limits the blast radius. If a Tier 1 user makes a mistake, they haven't accidentally leaked the entire customer database because they never had access to it in the first place.
The Hidden Risks: Prompt Injection and Stitching
Access control isn't just about blocking bad actors; it's about preventing accidental leaks. One major issue is "data stitching." Imagine User A asks the AI about Project X. The AI retrieves a document about Project X. Later, User B asks about Project Y. The AI retrieves a document about Project Y. If the system caches context poorly, or if the model retains session memory incorrectly, User B might see details from Project X. Modern access controls must ensure strict session isolation.
Then there's prompt injection. Malicious inputs can trick a model into ignoring its instructions. A study by Oligo.security found that 38% of enterprise deployments faced prompt injection attempts. If your access control relies solely on the model's "politeness" or instruction-following, it will fail. You need proxy-based firewalls that inspect the payload before it even hits the LLM. These firewalls look for patterns like "ignore previous instructions" or unexpected JSON structures that suggest an attack.
Compliance and The Cost of Over-Securing
If you operate in Europe, GDPR Article 32 requires "technical safeguards that limit exposure to only what's necessary." If your LLM sends all prompts to a US-based server without proper anonymization, you might be non-compliant. Similarly, HIPAA demands strict controls over PHI. Failing to implement granular access controls can result in fines that dwarf your AI budget.
However, beware of over-securing. Cerbos.dev notes that excessive restrictions can reduce the utility of LLMs by 30-40%. If employees have to submit tickets every time they want to try a new feature, they'll stop using the tool altogether. The goal is frictionless security. Automated policy generation-where an AI helps write the rules-is becoming popular, with 63% of security vendors developing this feature. It helps balance usability with safety by suggesting reasonable defaults based on usage patterns.
Getting Started: A Practical Checklist
Don't try to boil the ocean. Start small. Here is a roadmap for implementing effective LLM access controls:
- Audit Current Usage: Find out who is already using AI tools. Many employees use personal accounts for work tasks (Shadow AI).
- Classify Data Sensitivity: Define what data is "public," "internal," and "confidential." Map this to your LLM providers.
- Implement a Gateway: Deploy a centralized proxy to manage API keys and log traffic. This gives you visibility.
- Start with RBAC: Assign basic roles. Restrict premium models to power users first.
- Add Guardrails: Implement filters for PII (Personally Identifiable Information) and sensitive keywords.
- Monitor and Iterate: Review logs weekly. Adjust permissions based on actual behavior, not assumptions.
Remember, the technology moves fast. NIST updated its AI Risk Management Framework in November 2025 to include specific access control requirements. Staying compliant means staying flexible. You aren't building a static wall; you're managing a flow of information. Treat your LLM access controls as a living part of your security architecture, not a one-time setup task.
What is the main difference between RBAC and CBAC for LLMs?
RBAC (Role-Based Access Control) grants access based on who the user is (e.g., Manager, Intern). CBAC (Context-Based Access Control) adds layers of complexity by checking what the user is asking, what data the model is retrieving, and what output is generated. CBAC is necessary for preventing data leakage in complex workflows where the same user might handle both public and sensitive information.
Do I need different access controls for different LLM providers?
Yes, especially if you use a multi-provider strategy. Each provider (OpenAI, Anthropic, Google) has different data retention policies and security features. Using a centralized gateway allows you to apply consistent policies across all providers, ensuring that a restriction applied to one model applies logically to others, reducing management overhead.
How does prompt injection affect access controls?
Prompt injection involves malicious inputs designed to bypass existing instructions or security filters. Standard access controls might allow a user to send a prompt, but injection attacks can force the model to reveal restricted data or perform unauthorized actions. Effective security requires proxy-level inspection of prompts before they reach the LLM to detect and block these patterns.
Can LLMs themselves manage access controls?
Emerging solutions use LLMs to analyze access logs and detect anomalies, achieving high accuracy in identifying unusual patterns. However, relying solely on LLMs for real-time authorization decisions is risky due to latency costs and the potential for hallucinations. Most experts recommend a hybrid approach: use traditional logic for immediate blocking and LLMs for post-event analysis and policy refinement.
What is 'data stitching' in the context of LLM security?
Data stitching occurs when an LLM combines information from multiple sources or sessions in ways that expose sensitive connections a user shouldn't see. For example, if a model remembers a detail from a previous conversation with another user due to poor session isolation, it might inadvertently link two separate pieces of confidential data. Proper access controls ensure strict session boundaries to prevent this.